Structured Data Extraction via JSON Schema in Agent Tools
JSON schemas enforce extraction contracts that survive site redesigns.
An AI agent that pulls data from the web needs a guarantee, not a set of instructions for where to look. Selector-based extraction, the old pattern of telling a scraper "find this CSS class, walk this DOM path," gives an agent a procedure instead of a contract, and procedures break the moment a site redraws its markup.
Picture a pricing page where the class name changes from .product-price-large to .price-tag-new during a routine front-end update. The selector that used to find the price now finds nothing. It doesn't throw an error. It returns null instead, so the agent keeps going and feeds a missing value into whatever reasoning step comes next. The corruption is silent, which is worse than a crash, because nobody notices until a downstream decision is already wrong.
A human developer catches this kind of thing because a human developer can read the new markup, spot the renamed class, and patch the selector in ten minutes. Agents need a contract that holds regardless of how the page is built.
What schema-declared extraction means
Schema-declared extraction means you define a JSON schema before the extraction layer ever runs, so the system knows what to return. The schema specifies the shape of the output: field names, types, which fields are required, which are optional, how nested objects and arrays are structured. It says nothing about where on the page to find any of it. That's the whole shift: the contract describes the output, not the retrieval path, so it survives a redesign that would snap any selector.
Compare that to the prompt-only approach most teams start with, where the instruction to an LLM is some version of "return JSON with these fields." Field names drift between calls. Downstream code that assumes a stable structure has no actual guarantee that structure will hold, because nothing enforced it. Any developer who has shipped a prompt-only JSON integration and then watched production throw a KeyError on a field that was there yesterday already knows this gap first-hand.
The real test for any extraction API is whether it enforces the schema at the token level, constraining what the model can generate so the output literally cannot violate the shape, or whether it just asks the model nicely and hopes. Context enforces JSON schemas at the token level through constrained decoding, so the extraction layer returns a conformant object in a single API call. A prompt-only pipeline that fails validation often needs a second LLM call just to repair and restructure the first attempt, doubling latency and cost on every failure. Schema enforcement turns the contract from something the model is asked to honor into something the output cannot fail to satisfy, which is what lets downstream agent reasoning depend on the structure without checking it first.
Schema quality as the real production variable
Nearly every extraction tool on the market now advertises schema support. Pipeline reliability in production depends on the quality of the schema written for it, not on whether the underlying tool can technically enforce one. Teams routinely test against their simplest schema, a flat object with three or four obvious string fields, and conclude the pipeline works. That test proves nothing about where the system breaks, because a real schema has nested objects, ambiguous field boundaries, and nine optional fields deep in nested array.
Amazon's PARSE research names the actual source of this failure. JSON Schema was designed as a contract between human developers and static systems: a backend team and a frontend team agreeing on an API shape, enforced by a parser that either accepts or rejects a payload. It was never designed as an instruction set for an LLM agent trying to figure out which paragraph on a page maps to which field. When a schema's field descriptions are vague or its entity boundaries are unclear, an LLM doesn't fail loudly. It hallucinates a plausible-looking value that fits the type and passes validation.
That gap is visible in the measured numbers below. Under its judge-in-the-loop configuration, xmemory measured 62.67% output accuracy on its structured extraction benchmark, the best score among all the frontier structured-output baselines it tested. Reading that number straight: on a single pass, even the best approach gets the full object exactly right well under two-thirds of the time. Syntactic validity and semantic validity are different properties, and only one of them is checked by a schema conformance test.
There's an objection buried in this, and it deserves to be taken seriously rather than waved off: forcing a model to hit a rigid schema may pull its attention away from understanding the content itself. Pulling a model's attention toward a rigid schema can cost it some understanding of the content itself.
The resolution is that the reliability gained from constrained decoding still outweighs the semantic noise it introduces, for one concrete reason: the alternative is free-text generation, where errors aren't just possible but compound silently at every downstream step with no gate to catch them. Schema quality is the actual engineering problem. Fixing it is a design discipline, not a procurement decision.
Designing a JSON schema that holds up in an agent extraction pipeline
Design the schema around what the downstream reasoning needs, not around whatever the source page happens to display. Decide first what the agent needs to reason over, then build the schema to deliver exactly those fields. Normalization belongs in the step that needs the normalized value, not jammed into extraction where it adds another point of failure.
Field naming earns more weight than it gets. A minimal field definition makes the principle concrete:
"base_price_usd": {
"type": "number",
"description": "The item's listed base price in US dollars, excluding tax and shipping.",
"required": true
}
Mark a field required only when its absence should count as a hard failure worth stopping the pipeline over. Everything else should be optional with explicit null handling, so if a source page simply doesn't list a shipping date, that doesn't cascade into a broken run. A vague description is where a hallucination gets a foothold.
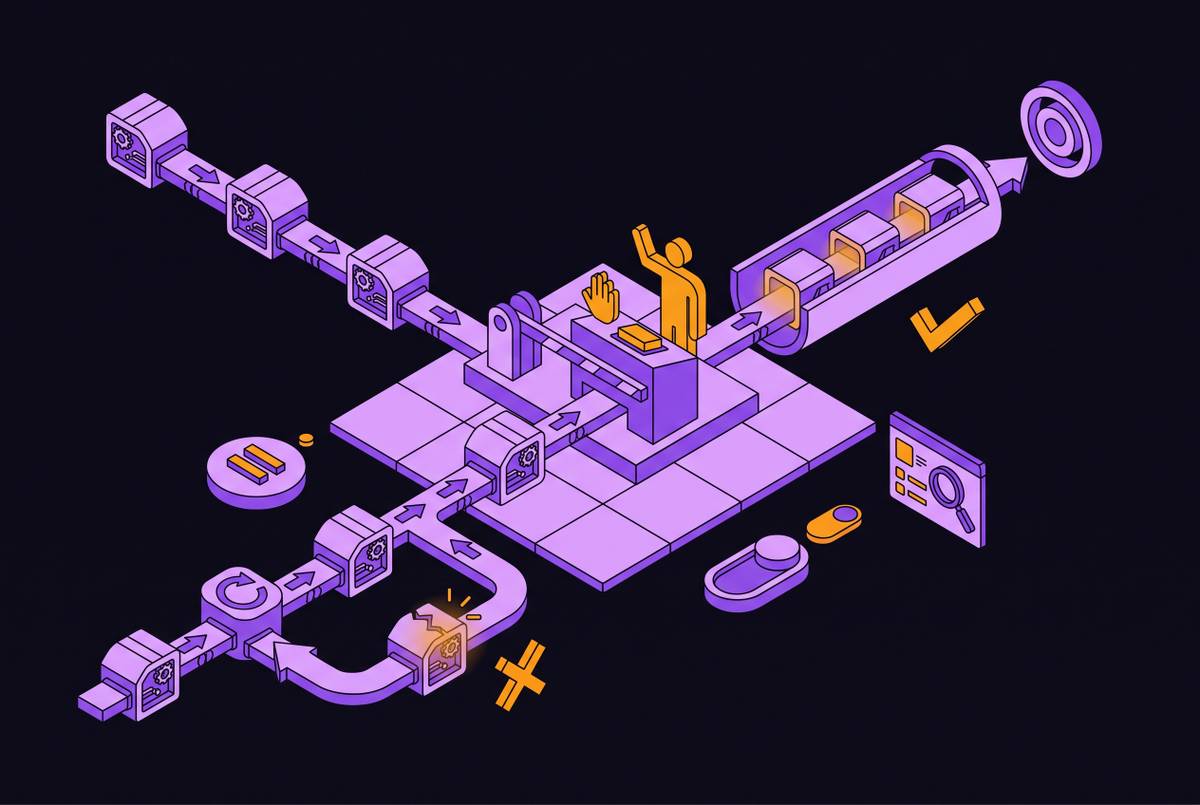
Single-pass extraction has a ceiling, as the earlier numbers showed. An iterative, schema-aware write path, one that splits the job into separate passes for object detection, field detection, and field-value extraction, with validation gates and local retries between each, closes a lot of that gap. The xmemory research reports 90.42% object-level accuracy with that decomposed approach, a sizable jump over single-pass performance on complex schemas.
Treat a schema as something that evolves, not something written once and left alone. Test every schema against the hardest case it has to handle, a page with inconsistent formatting, missing optional sections, ambiguous entity boundaries, because the easy case was never where the pipeline was going to break.
Wiring schema-declared extraction into an agent tool definition
The schema belongs inside the tool definition, not bolted on afterward as a validation step. Declare it at the tool layer, and the schema becomes the tool's return type. An agent calling that tool gets back a typed, predictable object it can hand straight to the next reasoning step without stopping to inspect it first, the same way a typed function signature tells calling code what it's getting back before the function ever runs.
A tool definition built this way needs three things: the target URL or URL pattern, the JSON schema describing what to extract, and any rendering requirements, JavaScript rendering for a page that builds its content client-side, for instance. A sketch of that shape looks like this:
{
"tool": "extract_structured_data",
"url": ",
"render_js": true,
"schema": {

}
}
A web scraping API built for agent pipelines absorbs everything that definition requires: proxy rotation, a headless browser, stripping out navigation and boilerplate, before the schema ever gets applied. Context turns a URL into LLM-ready structured JSON through one API call, with no proxy infrastructure, crawler, or parsing layer to build separately. For a known page with a fixed structure, that means calling Scrape with formats.json: true and a JSON Schema set in jsonParams.schema, then reading json.data back and validating it before anything downstream touches it.
If agents discover tools at runtime rather than having them hard-coded, they need a different surface. Context exposes its tools over MCP, so an agent discovers and invokes extraction tools through the protocol directly, driven by natural-language input to the LLM. A direct REST call is the better fit for high-throughput batch jobs: predictable latency and reliable pagination, where MCP adds a layer of reasoning latency that current agents don't always handle well, particularly on pagination. The choice is a per-workload decision, not a universal one.
How many tools an agent has to choose from matters as much as schema quality. Scope extraction tools around schema families, one tool per structural pattern, not one tool per target site. And you validate the returned object against its schema at the tool boundary, before the result ever enters the agent's reasoning context. A conformance failure caught at the boundary is a handled error the agent can retry or escalate. A malformed object that slips past the boundary and into reasoning context is corruption with no flag on it.
Schema-grounded extraction for brand and structured entity data
The same pattern applies once an agent needs to reason about the entity behind a URL. A company name, a logo, a brand color, an industry classification: these aren't things prompt-only extraction handles well, because they're scattered across a page in formats built for human eyes, not a plain-text summary a model can read off.
An agent building a company profile, scoring a sales lead, or enriching a data record needs a logo in a specific file format, a brand color as a hex value, a company description, social links, and an industry classification, all as typed fields it can act on directly, not raw HTML it has to go mining through. Context extracts exactly that set, logos, brand colors, fonts, company descriptions, social links, and industry classifications, as typed fields. For an agent scoring a lead or assembling a company profile, that structured brand data arrives ready to plug into the next step.
The underlying pattern doesn't change at all from page-content extraction. Declare the fields the agent actually needs, a logo URL, a primary color hex code, a set of industry tags, a canonical company name, call the extraction endpoint, and get back a conformant object. The agent's downstream step receives that same guaranteed structure no matter how wildly the source domain's homepage presents the information visually. This is a corner of structured web data that's genuinely underserved: general-purpose scrapers hand back raw HTML, and general-purpose LLM extraction tends to miss the specialized signals, CSS-extracted color values, SVG-embedded logos, meta tag descriptions, that brand intelligence actually depends on.
Schema-declared extraction as the foundation for change detection and live web grounding
Agent reasoning degrades fast when it runs on stale data, which makes freshness a first-order design constraint, not an afterthought. The fix that works in production is retrieval: feeding an agent live web data at query time, so its answers rest on current sources. A stable schema is what makes that retrieval trustworthy enough to automate.
A typed, consistent extraction output turns change detection into a deterministic diff. Run the same schema against the same page today and tomorrow; any change in a field value is a real change. The workflow is straightforward: extract a baseline object, store it, re-run extraction against the identical schema on a schedule, diff the field values, and fire an alert only when something material moves. Pricing, product claims, availability, and policy language sit inside the schema as explicit fields. Timestamps, navigation labels, and decorative copy don't, so they never trigger a false alert.
Strip the schema out of that picture and change detection collapses back into raw HTML diffing, which flags every layout tweak, every A/B test variant, every rotating ad impression as a potential change. That produces so much alert fatigue that teams stop trusting the alerts, which defeats the entire point of automating the check.
Testing schema quality properly means running extraction across a wide, messy set of real-world sources, not just the one clean page a schema was designed against. Most teams skip that step because building and maintaining test coverage across dozens of live sites is its own infrastructure project. A platform built for agent data pipelines handles the crawl and extraction at that scale directly, surfacing schema brittleness during testing. That's also where the unified API pattern pays off end to end: one API key covering the crawler, the Markdown conversion, the structured extraction, and the brand enrichment layer, with the same schema traveling across every stage, from the first crawl through months of ongoing monitoring, with no proxy pool or browser fleet for a team to run on its own.
Schema-declared extraction is the right primitive for agents because it makes an agent's model of the web inspectable and diffable over time, not just accurate at the moment of first extraction. If an agent reasons well today but silently drifts into reasoning on broken data next month, the freshness problem remains unsolved. The schema is what keeps that from happening.